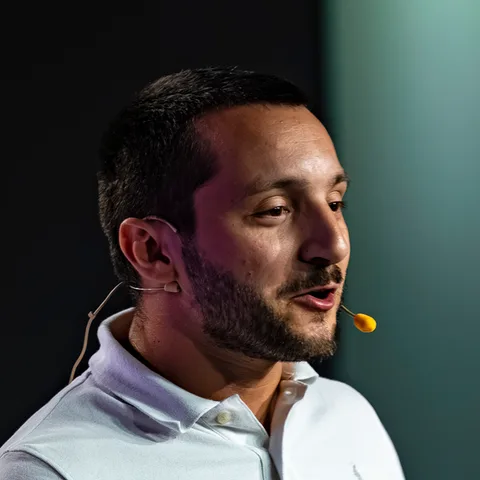
Benjamin Ameztoy
> Observability · Platform Engineering · Agentic AI
You can't master what you can't see. I build the platforms that give engineering teams the visibility they need — at scale, in production.
- OBSERVABILITY
- OPENTELEMETRY
- KUBERNETES
- AGENTIC AI
From South-West France
to distributed systems.
I grew up in South-West France, in a culture where you say things to people's faces and where collective commitment is not a slogan — it is a given. Rugby shaped the way I move forward long before code did.
For several years now I have been designing and operating large-scale observability platforms at Cdiscount. What drives me: making complex systems legible and reliable, and making the teams who run them autonomous.
Today I am looking towards agentic AI with the same conviction: a system you cannot observe is a system you cannot trust.
Rugby taught me that a scrum holds or collapses together. I build platforms that serve teams, and I pass on as much as I produce.
Metrics, logs, traces: every signal counts. Without observability you react. With it, you anticipate.
Solid foundations free teams up for what actually matters. An industrialised good practice beats one-off heroics.
Autonomous systems need to be traceable and explainable. Observability will be the bedrock of AI in production.
Commit after commit.
Vision and roadmap for shared on-premise observability platforms. Leading the migration to OpenTelemetry, designing resilient architectures, defining standards and supporting engineering teams.
Building and scaling shared observability platforms. Overhauled how those platforms are industrialised.
Joined the Observability component team. Contributed to the evolution of high-volume metrics and logs platforms.
Maintenance in operational condition of a medical imaging solution deployed across many sites in France. Incident handling and service continuity in a critical environment.
What I bring.
From design to operations, I cover the full lifecycle of the platforms.
Gathering needs from engineering teams and turning them into technical requirements and architecture options. Comparing solutions, trading off cost, complexity and delivery time, running proofs of concept to decide before building.
Designing and running centralised platforms covering metrics, logs and traces. Resilient architecture, high availability, lifecycle management — from Prometheus to OpenTelemetry.
Building internal platforms that accelerate product teams. Technical roadmap, standards and adoption patterns to industrialise platforms across a multi-team organisation.
Observability as the foundation of AI systems in production. Decision traceability, behavioural anomaly detection, explainability at scale.
Daily tools.
What I share.
A platform nobody understands delivers only half its value. I write and speak about what I build: concrete field reports, architecture decisions I stand behind, and what they actually cost. Open to conversations and invitations.
Collecting metrics from batch jobs and cron tasks that Prometheus pull mode cannot reach: a hybrid push/pull architecture, without inflating the infrastructure bill.
The story of an on-premise observability platform built from scratch: how it absorbed massive volumes and the move to OpenTelemetry by treating observability as a product — and how AI now runs in daily operations, from anomaly detection to PromQL assistants and generated dashboards.
Let's talk.
Got a project, an opportunity, or simply want to talk observability or agentic AI? I am available.
[ CONTACT ME ON LINKEDIN → ]